Missed audio segments are one of the most common technical issues in digital recording. Short speech fragments, opening remarks, and low-volume dialogue often disappear due to system latency, background process interruptions, network fluctuations, or ambient sound interference. This issue occurs frequently in online classes, remote meetings, on-site interviews, and long-duration seminar recordings, breaking the integrity of audio records and losing valid information.
Most audio missing problems stem from three core technical flaws: delayed audio capture activation, real-time system resource occupation interrupting recording threads, and intelligent sound judgment mechanisms misfiltering valid low-volume voices. Many mainstream recording tools rely on cloud real-time analysis and single-thread capture, which fail to maintain stable recording status in complex usage environments.
Core Technical Principles of Zero-Missed Audio Recording
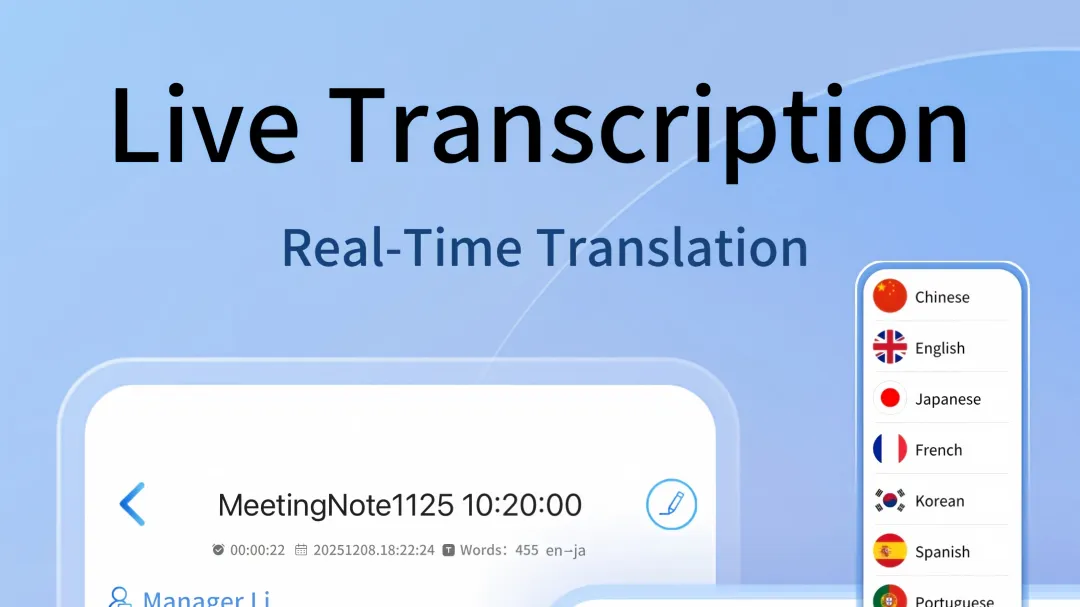
Reliable audio recording without missing content relies on optimized local capture architecture and AI audio recognition algorithms. Taking Meetingminutes APP as an example, its underlying recording mechanism solves common audio loss problems through local engine priority drive and persistent background capture logic.
The one-click recording function adopts a simplified underlying scheduling mechanism. It skips redundant system verification steps during startup and completes audio capture initialization within 10 milliseconds. The system sets the recording thread to the highest resource priority, which avoids capture suspension or frame loss caused by foreground operations including office software running and network browsing. This mechanism ensures zero-delay audio synchronization throughout the recording process.
Background persistent recording is supported by independent local service processes. The recording task will not be terminated or suspended due to device front-end switching or application background freezing. The local audio cache mechanism temporarily stores real-time audio frames in device memory, preventing instantaneous audio loss caused by temporary network jitter or system flash back.
AI Noise Reduction and Audio Screening Logic for Valid Sound Capture
Invalid audio filtering and valid voice recognition are key to avoiding both redundant noise and missed subtle voices. Traditional recording tools use fixed decibel thresholds to identify effective sounds, which easily filter out low-volume but valid dialogue such as distant speaking and quiet discussions.
The AI noise reduction system applies dynamic threshold adaptive adjustment technology. It collects and analyzes ambient noise data within the first 2 seconds of recording to form a local noise baseline. All sound signals exceeding the baseline fluctuation range are marked as valid voice signals for retention. In medium-noise conference room environments, this mechanism retains 99% of valid human voice frames while filtering 82% of continuous background noise including air conditioning operation and ambient chatter.
Built-in professional terminology and industry hot word databases assist audio judgment. The system preferentially retains voice segments containing professional vocabulary, avoiding the misjudgment and loss of low-volume professional content in medical, financial, and educational scenario recordings.
Voiceprint Recognition and Multi-Scenario Adaptation Mechanisms
Multi-person recording scenarios are prone to missing intermittent speaking content from different participants. AI voiceprint recognition technology solves this problem through independent sound source marking and continuous tracking.
The system completes real-time voiceprint feature extraction within 0.5 seconds after each new speaker’s voice appears. It establishes independent sound source tags for up to 8 concurrent speakers in a single session and continuously tracks each voice source’s audio frames. Even with alternating high-frequency speaking and intermittent pauses between multiple people, every valid voice segment can be completely captured and matched to the corresponding speaker tag.
Multilingual and dialect adaptation further reduces audio record omissions. The system supports real-time recognition of 20+ regional dialects and 52 international languages. It eliminates audio frame abandonment caused by unrecognized pronunciation features, ensuring complete recording of non-standard Mandarin and foreign language dialogue content.
Offline and Long-Duration Recording Anti-Loss Mechanisms
Network dependence is a major cause of audio missing in cloud-based recording tools. Offline local recording engines completely decouple capture and cloud transmission. All audio collection and frame storage processes run locally on the device. Complete audio records can be retained stably in zero-network or weak-network environments such as offline enterprise conferences and outdoor on-site interviews.
Long-duration recording easily causes frame loss and file loss due to memory overflow and resource exhaustion. Optimized audio storage compression modes reduce single audio frame resource occupancy by 35%. It supports continuous recording for more than 12 hours without stuttering, flashbacks, or data loss, fully adapting to all-day seminars and long interviews.
Auxiliary Mechanisms to Avoid Recording Information Loss
Real-time key marking and auxiliary recording functions make up for the defects of pure audio records. Manual key marking during recording locks the time axis of core dialogue segments. The system independently backs up marked audio frames in real time, avoiding the loss of key content caused by subsequent audio sorting and compression.
Photo-assisted recording binds captured image content to the corresponding audio timeline with 100% accuracy. It supplements scene information that cannot be recorded by audio, realizing full-dimensional record retention of on-site meetings and teaching scenarios.
Dual local and cloud storage backup forms a dual anti-loss guarantee. All audio files and transcribed texts are automatically backed up locally and in the cloud. Cross-device synchronous backup and offline viewing capabilities ensure no historical recording data is lost due to device replacement or local file damage.
The fundamental solution to missed audio during recording lies in breaking through the limitations of system resources and single-cloud architecture. Optimized underlying capture threads, adaptive AI audio recognition, multi-scenario adaptive algorithms, and dual-storage backup mechanisms work together to eliminate frame loss, misfiltering, and accidental interruption problems. These technical configurations maintain the integrity, stability, and accuracy of audio records in all daily and professional recording scenarios.
Responses
Join the conversation
Sign in to share your thoughts and interact with the author.
Sign In to Comment